or go to full-text search page →

Search

Search IconIcon to open search

Querying HackerNews with DuckDB directly (HackerTube, HackerBooks & Wikihack)

Last updatedUpdated: by Simon Späti · CreatedCreated: · 5 min read · growing Note status Growing. Worked on quite a bit, still rough. Expect bullets, gaps and views that update. Estimated from edit history · 2 sessions over 1 day · 1,077 words · How my notes grow Recent changes today +6 / −10 words today published · 1081 words

Reading Karpathy’s HackerTube, and then seeing a bunch of other apps on top of Hacker News like HackerBooks and Wikihacks:
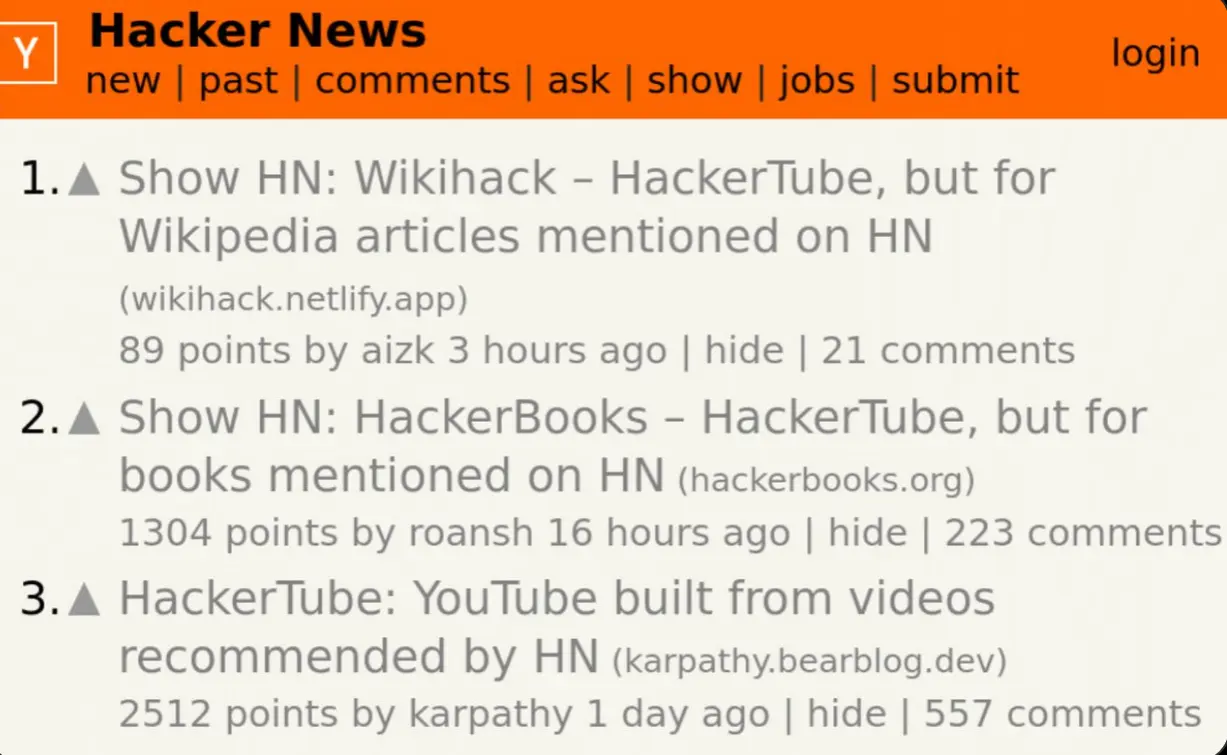
Karim Jedda noted on X “simpler to just publish the curated/filtered down datasets and let client” do the rest. That got me thinking: the dataset is public on Hugging Face, and with DuckDB we can just query it directly from your terminal.

Let’s see how that looks and works.

# Querying all datasets from 2006-2026

Let’s read all rows available in that dataset for 2026 (run it yourself below with integrated DuckDB runner) - just replace 2026 with ** to read all data.


-- total across all years
SELECT count(*) AS total
FROM 'hf://datasets/open-index/hacker-news/data/2026/*.parquet';

1
2
3
4
-- per year
SELECT regexp_extract(filename, 'data/(\d{4})/', 1) AS year, count(*) AS n
FROM read_parquet('hf://datasets/open-index/hacker-news/data/**/*.parquet', filename=true)
GROUP BY ALL ORDER BY year;

The result for the second query:

See the dataset on Hugging Face open-index/hacker-news · Datasets at Hugging Face, it’s also what Karpathy used for his HackerTube page, see below.

See also Querying Bluesky with DuckDB and SQL for querying other datasets with a single DuckDB query.

# Querying HN for My Mentioned Domains

1
2
3
4
5
6
7
8
INSTALL httpfs; LOAD httpfs;

COPY (
  SELECT id, type, time, "by", score, descendants, title, url, text
  FROM 'hf://datasets/open-index/hacker-news/data/**/*.parquet'
  WHERE regexp_matches(url,  'ssp\.sh|sspaeti\.com|dedp\.online')
     OR regexp_matches(text, 'ssp\.sh|sspaeti\.com|dedp\.online')
) TO 'hn_sspaeti.parquet';

Gives the result of story domains: ssp.sh 108, sspaeti.com 8, dedp.online 5.

type n first last
story 122 2021-03 2026-08
comment 32 2023-02 2026-08

Top stories by score:

score cmts title
499 241 Self-Host and Tech Independence
253 459 From M1 MacBook to Arch Linux (Omarchy)
226 81 Finding Flow
180 132 Will AI Replace Human Thinking?
123 19 Data Engineering Vault: 1000 Node Second Brain
108 100 Vim Language, Motions, and Modes Explained (2023)
101 79 My Obsidian note-taking workflow
84 22 Data modeling guide for ClickHouse
25 7 Travel Locally, Where You Are
14 1 Data Engineering Design Patterns (DEDP)

Rest ≤ 8 points. Posters: mostly articsputnik, then zazuke, sebg, sspaeti.

# HackerTube, HackerBooks & Wikihacks with DuckDB

Let’s now rebuild the HackerTube, HackerBooks & Wikihacks in three DuckDB queries, no UI needed 😉.

Latest full month is July 2026, so let’s try with that:

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
--1. HackerTube – YouTube videos
WITH links AS (
  SELECT unnest(list_concat(
    CASE WHEN url <> '' THEN [url] ELSE [] END,
    regexp_extract_all(replace(replace(text, '&#x2F;', '/'), '&amp;', '&'), 'href="([^"]+)"', 1)
  )) AS link
  FROM 'hf://datasets/open-index/hacker-news/data/2026/2026-07.parquet'
  )
  SELECT coalesce(nullif(regexp_extract(link, '[?&]v=([A-Za-z0-9_-]{11})', 1), ''),
                  regexp_extract(link, 'youtu\.be/([A-Za-z0-9_-]{11})', 1)) AS video_id,
         'https://youtube.com/watch?v=' || video_id AS url,
         count(*) AS mentions
  FROM links
  WHERE regexp_matches(link, 'youtube\.com/watch|youtu\.be/') AND video_id <> ''
  GROUP BY ALL ORDER BY mentions DESC LIMIT 10;

But this does not show all the titles so let’s use a more complex query:

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
-- shared: one row per link (story url + hrefs in comments)
CREATE OR REPLACE TEMP TABLE links AS
SELECT id, unnest(list_concat(
  CASE WHEN url <> '' THEN [url] ELSE [] END,
  regexp_extract_all(replace(replace(text, '&#x2F;', '/'), '&amp;', '&'), 'href="([^"]+)"', 1)
)) AS link
FROM 'hf://datasets/open-index/hacker-news/data/2026/2026-07.parquet';

-- 1) HackerTube: titles via YouTube oEmbed (no API key)
CREATE OR REPLACE TEMP TABLE top_videos AS
SELECT coalesce(nullif(regexp_extract(link, '[?&]v=([A-Za-z0-9_-]{11})', 1), ''),
                regexp_extract(link, 'youtu\.be/([A-Za-z0-9_-]{11})', 1)) AS video_id,
       count(*) AS mentions
FROM links
WHERE regexp_matches(link, 'youtube\.com/watch|youtu\.be/') AND video_id <> ''
GROUP BY ALL ORDER BY mentions DESC LIMIT 10;

SET VARIABLE yt_urls = (SELECT list('https://www.youtube.com/oembed?format=json&url=https://youtube.com/watch?v=' || video_id) FROM top_videos);

SELECT v.mentions, j.title, j.author_name AS channel, 'https://youtube.com/watch?v=' || v.video_id AS url
FROM top_videos v
LEFT JOIN read_json(getvariable('yt_urls'), filename=true, union_by_name=true, ignore_errors=true) j
  ON regexp_extract(j.filename, 'v=(.*)$', 1) = v.video_id
ORDER BY mentions DESC;

-- 2) Wikihack: title = url-decoded slug, no API
SELECT count(*) AS mentions,
       replace(url_decode(regexp_extract(link, 'wikipedia\.org/wiki/([^#?]+)', 1)), '_', ' ') AS title,
       'https://en.wikipedia.org/wiki/' || regexp_extract(link, 'wikipedia\.org/wiki/([^#?]+)', 1) AS url
FROM links
WHERE regexp_matches(link, 'wikipedia\.org/wiki/') AND title <> ''
GROUP BY ALL ORDER BY mentions DESC LIMIT 10;

-- 3) HackerBooks: ISBN -> OpenLibrary; ASIN/Goodreads -> URL slug
CREATE OR REPLACE TEMP TABLE top_books AS
SELECT coalesce(nullif(regexp_extract(link, '/dp/([A-Z0-9]{10})', 1), ''),
                regexp_extract(link, 'goodreads\.com/book/show/(\d+)', 1)) AS book_id,
       any_value(link) AS url,
       count(*) AS mentions
FROM links
WHERE regexp_matches(link, 'amazon\.[a-z.]+/.*dp/|goodreads\.com/book/show') AND book_id <> ''
GROUP BY ALL ORDER BY mentions DESC, book_id LIMIT 10;  -- tiebreak: ISBNs before ASINs

SET VARIABLE ol_urls = (SELECT coalesce(list('https://openlibrary.org/isbn/' || book_id || '.json'), ['https://openlibrary.org/isbn/0000000000.json']) FROM top_books WHERE book_id ~ '^[0-9]{9}[0-9X]$');

SELECT b.mentions,
       coalesce(j.title,
                nullif(replace(regexp_extract(b.url, 'book/show/\d+-([^/?]+)', 1), '-', ' '), ''),
                nullif(replace(regexp_extract(b.url, 'amazon\.[a-z.]+/([^/]+)/dp/', 1), '-', ' '), '')
       ) AS title,
       CASE WHEN j.title IS NOT NULL THEN 'openlibrary' ELSE 'url slug' END AS title_src,
       b.url
FROM top_books b
LEFT JOIN read_json(getvariable('ol_urls'), filename=true, union_by_name=true, ignore_errors=true) j
  ON regexp_extract(j.filename, 'isbn/(.*)\.json', 1) = b.book_id
ORDER BY mentions DESC;

And that looks like this:

# Other queries without title

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
```duckdb
--2. Wikihack – Wikipedia articles
WITH links AS (
    SELECT unnest(list_concat(
      CASE WHEN url <> '' THEN [url] ELSE [] END,
      regexp_extract_all(replace(replace(text, '&#x2F;', '/'), '&amp;', '&'), 'href="([^"]+)"', 1)
    )) AS link
    FROM 'hf://datasets/open-index/hacker-news/data/2026/2026-07.parquet'
  )
SELECT regexp_extract(link, 'wikipedia\.org/wiki/([^#?]+)', 1) AS article,
       'https://en.wikipedia.org/wiki/' || article AS url,
       count(*) AS mentions
FROM links
WHERE regexp_matches(link, 'wikipedia\.org/wiki/') AND article <> ''
GROUP BY ALL ORDER BY mentions DESC LIMIT 10;
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
--3. HackerBooks – Amazon ISBN/ASIN + Goodreads
WITH links AS (
    SELECT unnest(list_concat(
      CASE WHEN url <> '' THEN [url] ELSE [] END,
      regexp_extract_all(replace(replace(text, '&#x2F;', '/'), '&amp;', '&'), 'href="([^"]+)"', 1)
    )) AS link
    FROM 'hf://datasets/open-index/hacker-news/data/2026/2026-07.parquet'
  )
  SELECT coalesce(nullif(regexp_extract(link, '/dp/([A-Z0-9]{10})', 1), ''),
                  regexp_extract(link, 'goodreads\.com/book/show/(\d+)', 1)) AS book_id,
         any_value(link) AS url,
         count(*) AS mentions
  FROM links
  WHERE regexp_matches(link, 'amazon\.[a-z.]+/.*dp/|goodreads\.com/book/show') AND book_id <> ''
  GROUP BY ALL ORDER BY mentions DESC LIMIT 10;

# Further Reads


Origin: Karim Jedda on X, Blog – karpathy, HackerNews